


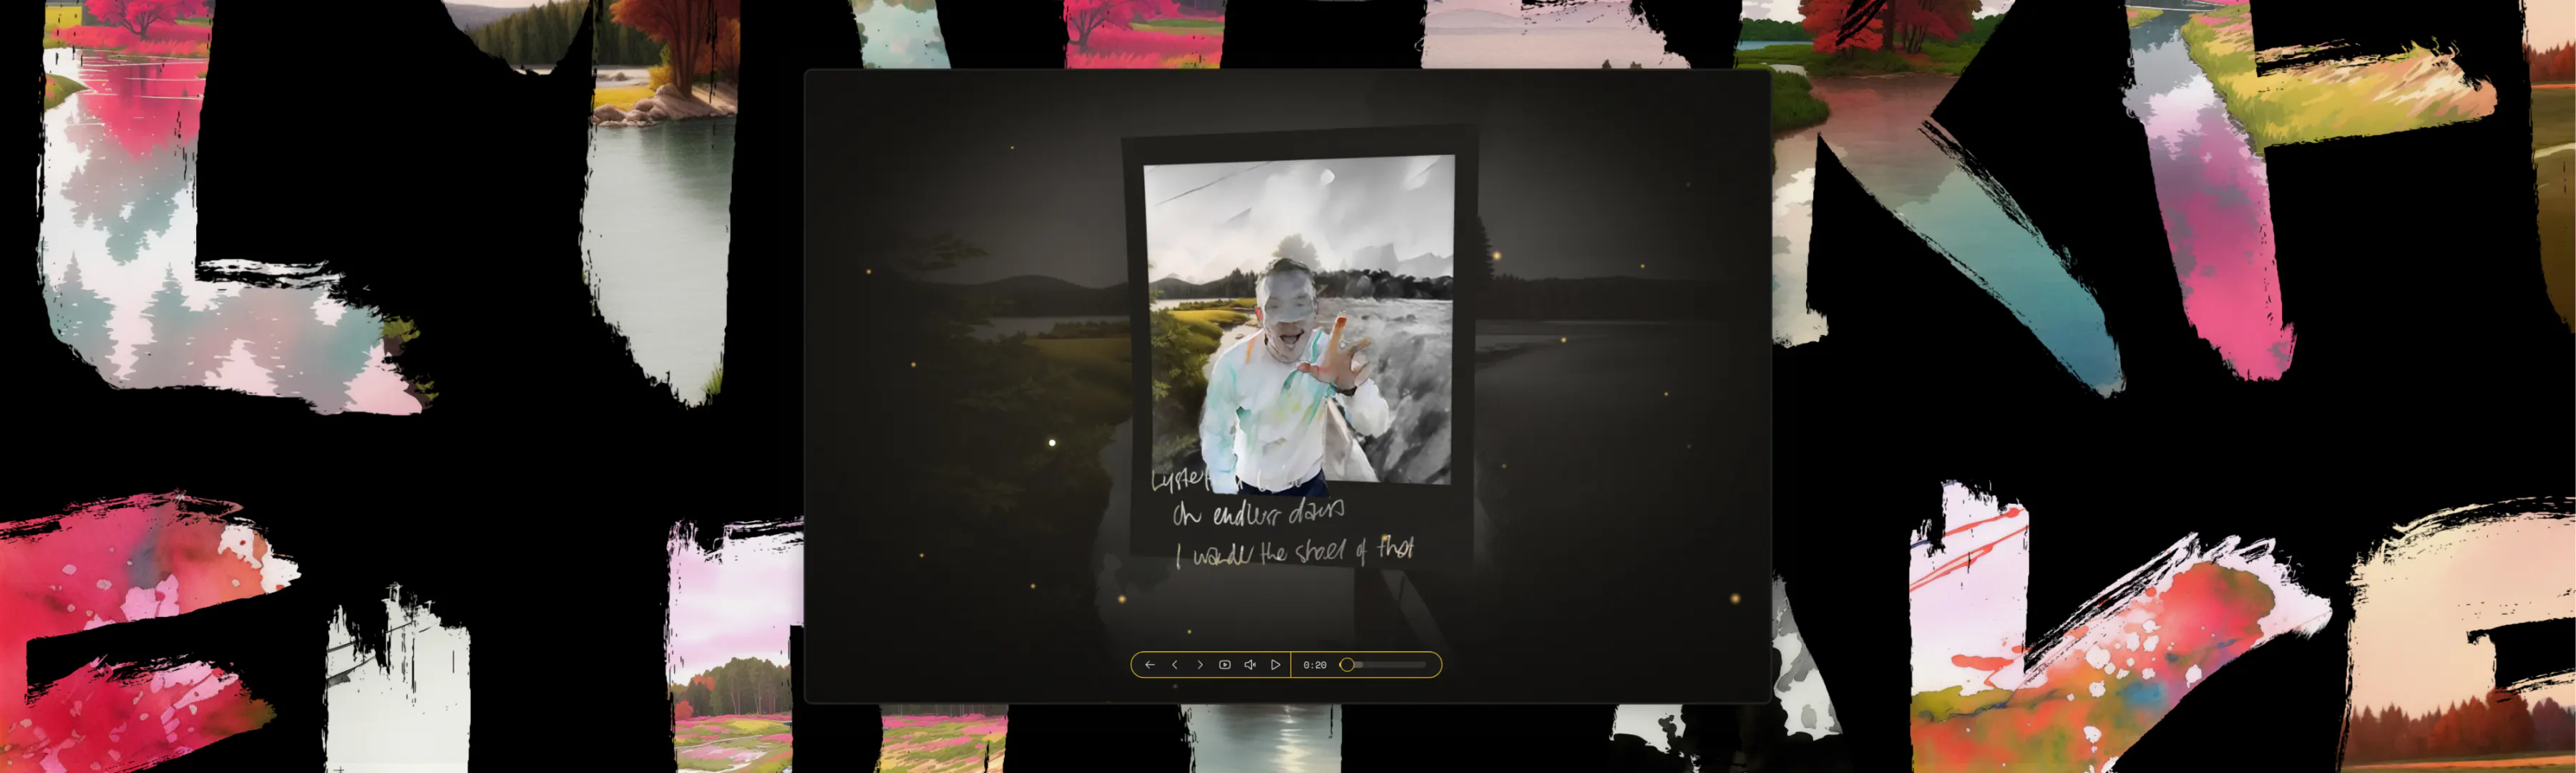

Lysterfield Lake is a song about a place outside Melbourne, Australia. It's about the endless summers of your youth, and the tiny changes in you that you don't even notice adding up. It's also about memories, which, like polaroids, fade and change over time.
I don't remember exactly when I wrote it in much the same way I don't remember exactly when I started this project, which spanned the better part of a year and all but consumed the most creative bits of my brain.
I think it all began when I came across Replicate (and by extension, their open-source container for running machine learning models, Cog.) I was so inspired by their Explore page, and, if I'm being totally honest, I was worried about the cost of experimenting with AI. I'd set up a gaming PC in the weird limbo of the 2020 lockdowns, and these tools made it effortless (and for the most part, free) to try, and test, and many, many times, fail.

Zoomable image
When I decided to release new music (it had been seven years since the last Brightly record) I knew I wanted to build something with these bits and pieces I'd been noodling with. I knew I wasn't great at making traditional music videos, and I've always felt empowered by the flexibility of the browser, and the creative opportunities afforded by using machine learning and AI. I think the result is something greater than the sum of its parts.
And there are a lot of parts.
(Also, if you haven't seen the video, you should go and check it out before I ruin the magic by shining a very bright light on exactly how it all works.)
(And if you'd rather check out a recording, you can jump over to YouTube to see a simplified version that should give you a pretty good idea.)

What is it?
Lysterfield Lake is a 3D generative interactive music video. It works in the browser, using Three.js and React Three Fiber to stitch together seven feeds of video frame by frame, turning a single piece of footage shot on an iPhone into a three-dimensional fever dream. It uses the accelerometer in your phone, if it's available, or your mouse if you're on a computer. It shows and hides the protagonist as you watch depending on your actions, offering a myriad of ways to experience it.
Each "dream" is a different painted world built from the same footage. There are twelve of them now, and since the relaunch you can swap between them mid-song, by grabbing the polaroid and flicking it away, without the music skipping a beat.
Behind the scenes it was modelled in Blender, (using a polaroid model by Edoardo Galati), generated by a pipeline of open models, and built in JavaScript. It is made up of entirely open-source projects that are freely available, and so is it.
It starts with choosing one. The dreams are a pile of polaroids, and dragging the top card aside tucks it under the pile to show the next.
Three years later
When I launched this in December 2023, I said new dreams could be added at any time. Then I didn't add a single one for almost three years.
It wasn't for lack of wanting to. The project shipped as two repos: a React app, and a pipeline I described, generously, as "not something that will work locally out of the box". In practice it was eight bash scripts chaining ffmpeg, three model servers and a custom PyTorch model running on the gaming PC under my desk, a hardcoded hostname for that PC, and a manual pass through Deforum and frame interpolation for every dream. Some of it only existed in my head, and my head had moved on.
So in August 2026 I started again. Ten weeks, 461 commits and 59 pull requests later, Lysterfield Lake lives in a single repo with the app, the pipeline, and the models it runs. The original app's history came along for the ride, so the first commit from November 2023 is still in there. The old repos are archived. And on 23 October 2026 the site relaunched with the first new dream since launch, Sharp Edges, followed four days later by a second, Oil Slick.
Digging up 2023
Before I could rebuild anything, I had to work out what I'd actually built. That meant an archaeological dig through an external hard drive, and then through a 202GB Linux backup, and it turned up some surprises. The matte had been a manual, undocumented step. The background wasn't a second shot, like I'd half remembered, but the same footage with me erased by three different models and a hand-placed click. And the prompts behind each dream were a time capsule of 2023: artist names, LoRA tags, and even Midjourney flags pasted in for good measure, none of which the model could possibly understand.
I also found where it all started: a test from March 2023, before I'd even gone to the lake. It's a selfie, two panels wide, run through the same watercolour model that ended up in the final video.
Most of the rebuild was pair-programmed with Claude Code. The repo carries a CLAUDE.md with the rules the project has learned the hard way, and a plans folder where every decision lives as a document, moving from backlog to done, with an honest record of what was actually built. It turns out the things that help an agent pick up a project are exactly the things that help a person do the same, including future me.
The process
So, how does it work? I made a diagram to help. This is how it worked in 2023, and most of it still holds. Where something has changed, I've noted it.

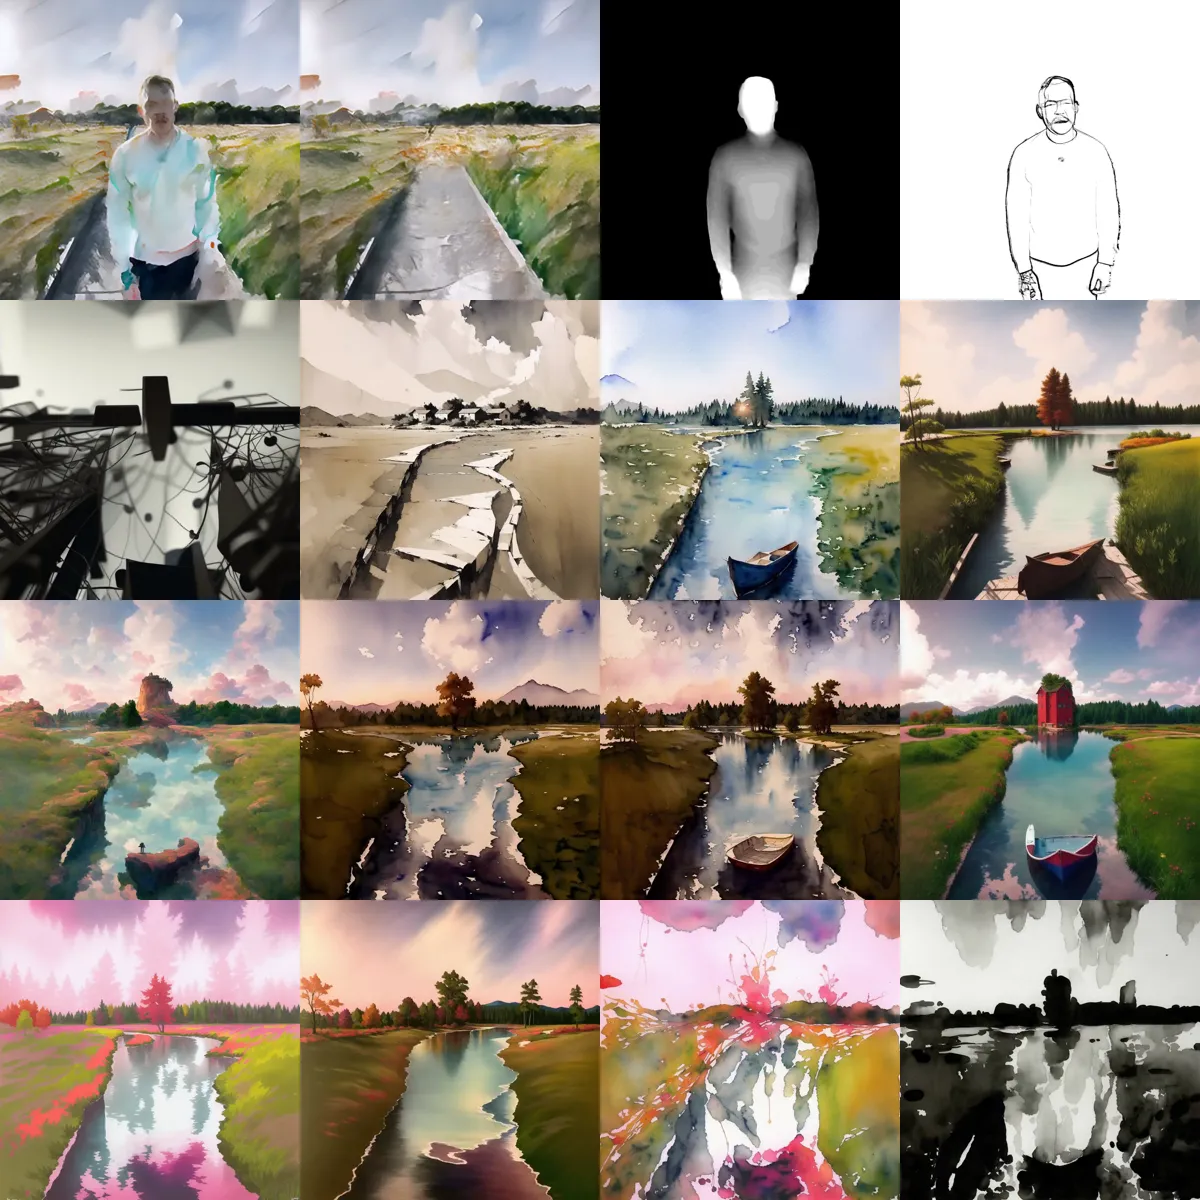
First, a single video file, shot on an iPhone, is split into individual frames. These frames then go through a bunch of processes depending on their final output, and come out the other side as seven panels of the same moment.
- Lyrics: handwritten, one line at a time.
- Portrait: the footage, repainted as watercolour.
- Background: the scene, with the person removed.
- Matte: a mask that cuts out the person.
- Depth: how far each part of the frame is from the camera.
- Outline: line art of the person.
- Dream: the whole scene reimagined as a painting, with no person in it.
In 2023 those were a set of scripts. Now they're a single TypeScript command-line tool, with one step per panel that you can run on its own against a job folder. Most steps call a model on Replicate, and every step skips any output that already exists. That rule exists because model calls cost money, a song is thousands of frames, and early in the rebuild a retry loop hammered the API for minutes before I noticed. Lesson learned.

The original footage vs the final output. Note to self: I probably should've gotten a haircut before this.
The Avatar
A 3D-watercolour version of the subject matter (which is, in this case, me).

Zoomable image
- DiffusionCLIP turns the image into a painted watercolour style.
- Robust Video Matting finds the subject in the video and creates an alpha mask of it.
- The mask is used with the original image and passed to ZoeDepth, which creates a depth mask.
- These three elements (the watercolour image, the alpha mask, and the depth mask) are used to render the avatar.

The depth panel is what lifts the avatar off the page, and in 2023 it had a habit of giving up. On the walk away it dropped to black for about half the stretch, and I went flat with it.
2023 Now
The Background
A watercolour version of the original image, without the subject matter.

Zoomable image
- Using the alpha mask and the original image, Inpaint Anything creates a version of the scene without the avatar in it.
- This inpainted image is then also painted in watercolour using DiffusionCLIP.
- This element is then used to render the background.

The hardest moment for the background is at 1:24, where my arms move fast enough to smear across anything that guesses frame by frame. Here's the painted portrait beside the background Bria makes for the same seconds, with me nowhere in it.
The Outline
A comic-book style sketch of the subject matter. It's the ink that sits over the painted avatar, so the figure keeps a hard edge against the background instead of melting into it, and it's what makes the 3D version read as a drawing rather than a render.

Zoomable image
- The original image is combined with the alpha mask to create a version with no background.
- This was fed into artline-torch, which created a rough outline sketch.
- This sketch is then overlaid on the avatar during rendering (it also uses a bit of dithering in a custom shader, which is what gives it the printed ink / slight comic book style).

The same fast arms are where the old outline struggled most, and where the swap shows best.
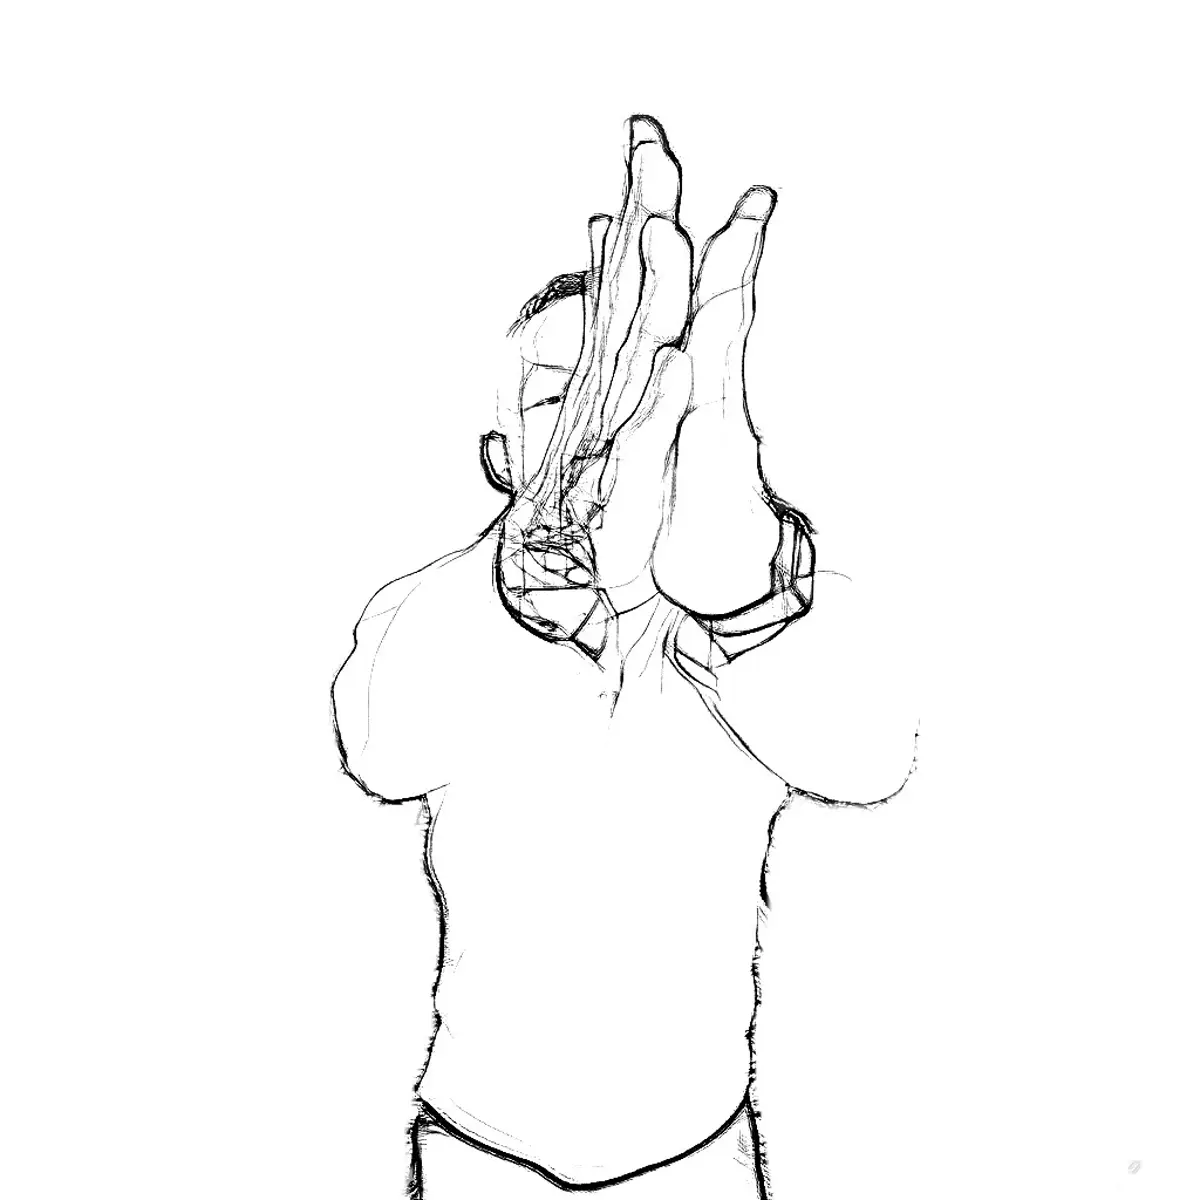
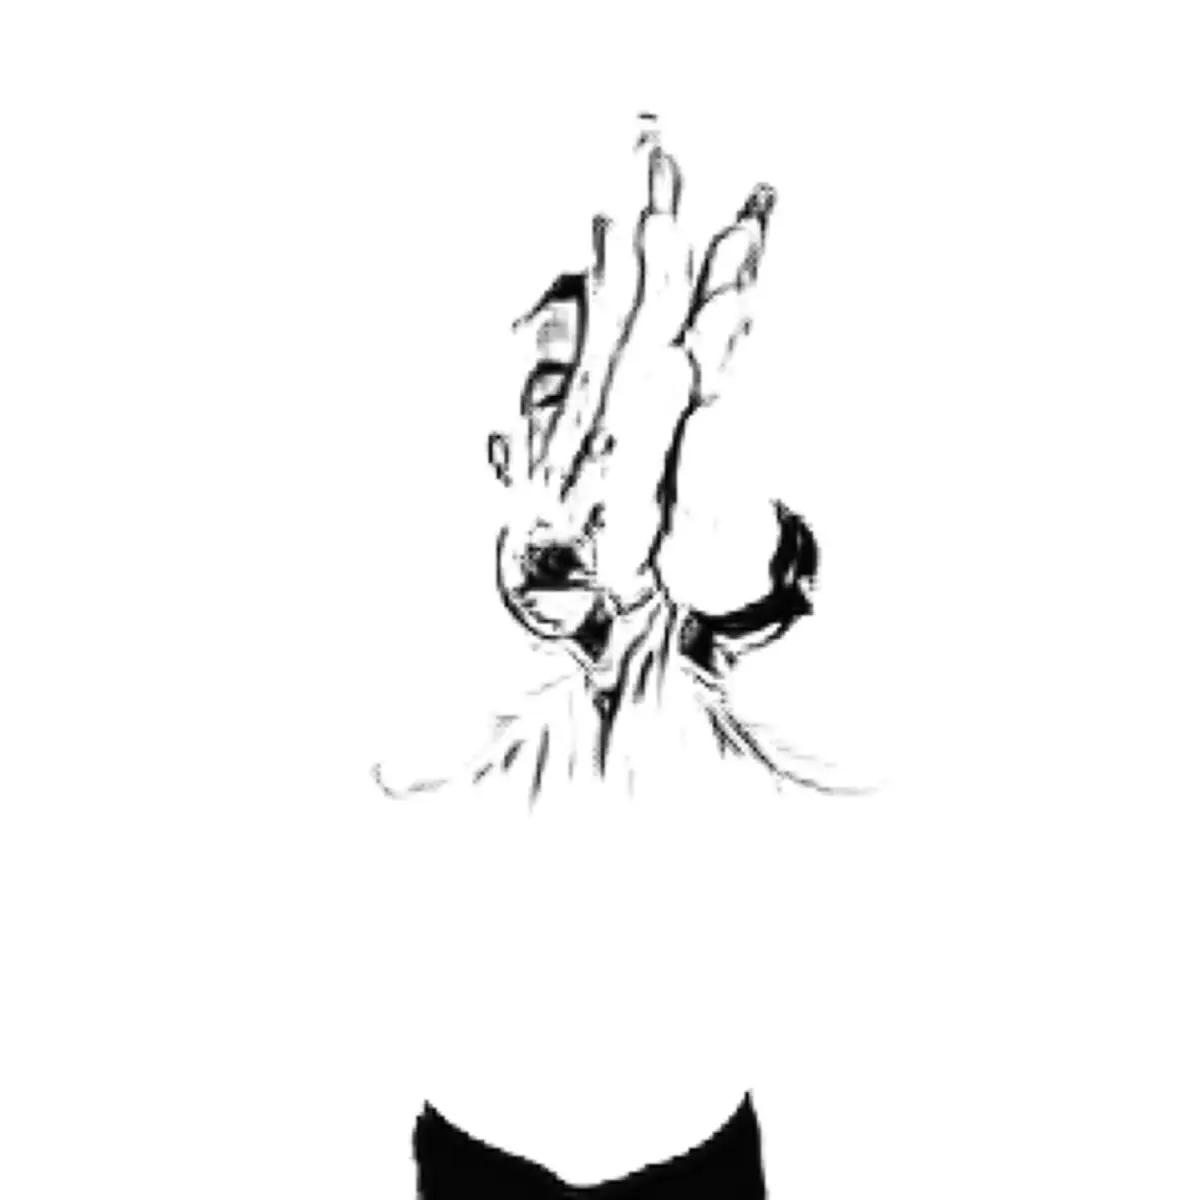 ArtLine Now
The Dreams
Prompt-generated reinterpretations of the original image.

Zoomable image
The original images are fed into Deforum Stable Diffusion, along with a prompt, creating unique scenes that mirror the subject matter. For example, trees and a lake that match the contours of the image.

In 2023, each frame was then manually reviewed one by one and removed if not appropriate. (The primary reason for this is that Stable Diffusion models are trained on image sets that include a large amount of waifus. Which, because the input clearly contains the shape of a person, means a lot of waifus end up in the output, even when politely asking Stable Diffusion not to.)

The remaining images were fed into rife-ncnn-vulkan, which interpolated the missing frames and generated new ones to fill the gaps.
That manual review is the part that had to change most, and it gets its own section below.
The Lyrics

At the same time, I recorded myself handwriting the lyrics in Procreate, and then cleaned them up in Adobe's After Effects.
(Apologies for my handwriting. I clearly should've been a doctor.)
The Output

In 2023, this got stitched together into an ultra-wide video with 7 square images side-by-side. Originally I tried using a single video for each element, but it's impossible to guarantee frame sync across multiple videos in the browser. Fortunately, much like how there's no rule against eating a candy bar on a dance floor, there's no rule that videos need to be 16x9. Using custom shaders in the browser, you can simply grab the crop of footage you need for each element in real time.
And having all of these elements in the one shader affords new opportunities. By passing the depth mask, alpha mask, and the watercolour scene, I was able to generate a rough 3D model.

Custom shaders essentially let you paint with pixels in real time, and it's an incredibly exciting medium once you start to explore the possibilities. It is how I can use the pixels from the depth mask to directly impact how close or far each fragment of the 3D avatar is. And, if you'd like to learn more, The Book of Shaders is a great resource.

The dreams, revisited
The first plan for the rebuild was to swap Deforum for something newer. Three years is a geological age in AI, and surely a modern video model would do it better, faster, and cheaper.
It didn't. Every new model I tried either kept me in the frame, or invented a whole new person standing in my pose. What makes the original dreams work, it turns out, is the subject's shape without the subject. A raised pair of hands becomes rock spires. A walking figure becomes a jetty. Head and shoulders become a red rock and its reflection in the lake. The newer models were too good at understanding what they were looking at.
So I rebuilt the exact Deforum setup from 2023, recovered from that backup down to the commit and the hand edits, and packaged it as the project's own model. It runs on Replicate, or on the 4090 PC in my house for free. The dreams can't be rendered in parallel, because each frame grows out of the one before it, so a full song is about 2,580 frames and six hours of patience.
Counting the waifus
Then came the uncomfortable bit. The new dreams kept showing a person, and I assumed I'd broken something. I hadn't. Replaced frames in the 2023 folders have later file dates than the rest, which meant I could count exactly how much hand-curation the originals needed: 1,322 of 21,480 frames, deleted and patched over by interpolation. Ink Flight needed none. Lush and Light needed nearly 17%, in 131 separate stretches.
The rebuild was faithful. What was missing was me, in 2023, squinting at thousands of frames.
So now that part is automated, and it learned from me. The person check is a small classifier on top of CLIP, trained on my own keep-or-replace decisions from 2023. It catches 97% of the frames I replaced, while flagging 1% of the ones I kept, and it checks a whole song in about six minutes on a laptop. Any stretch it flags gets rendered again with new seeds, never blended over, because interpolation smears the stop-motion look the dreams depend on.
The first repaired frame turned a clear figure from behind into a lake and a tree, in the dream's own palette.
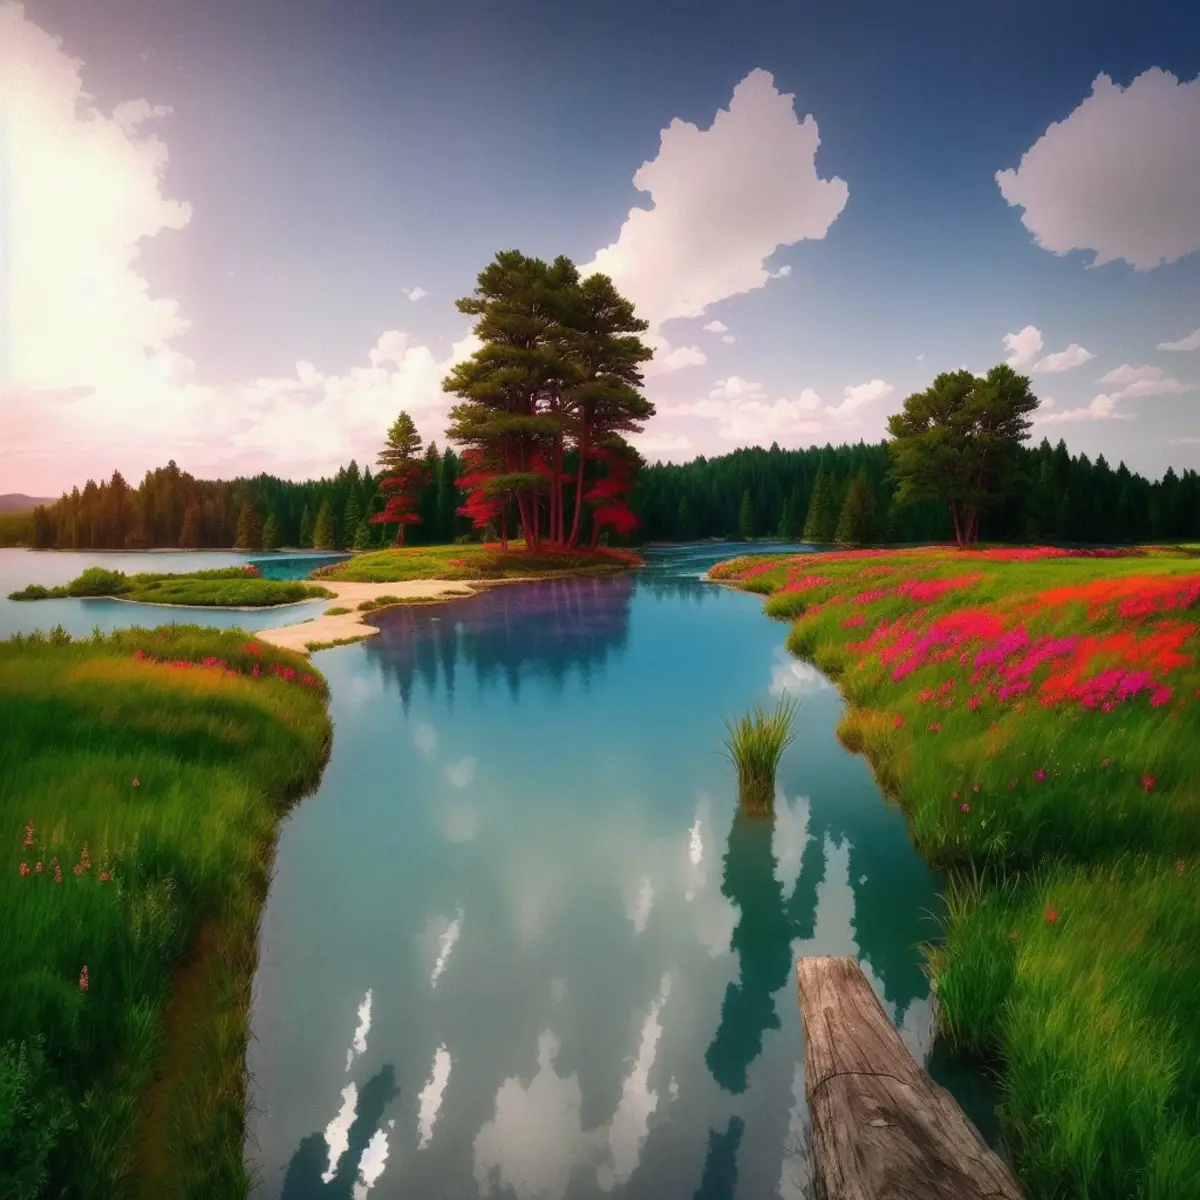
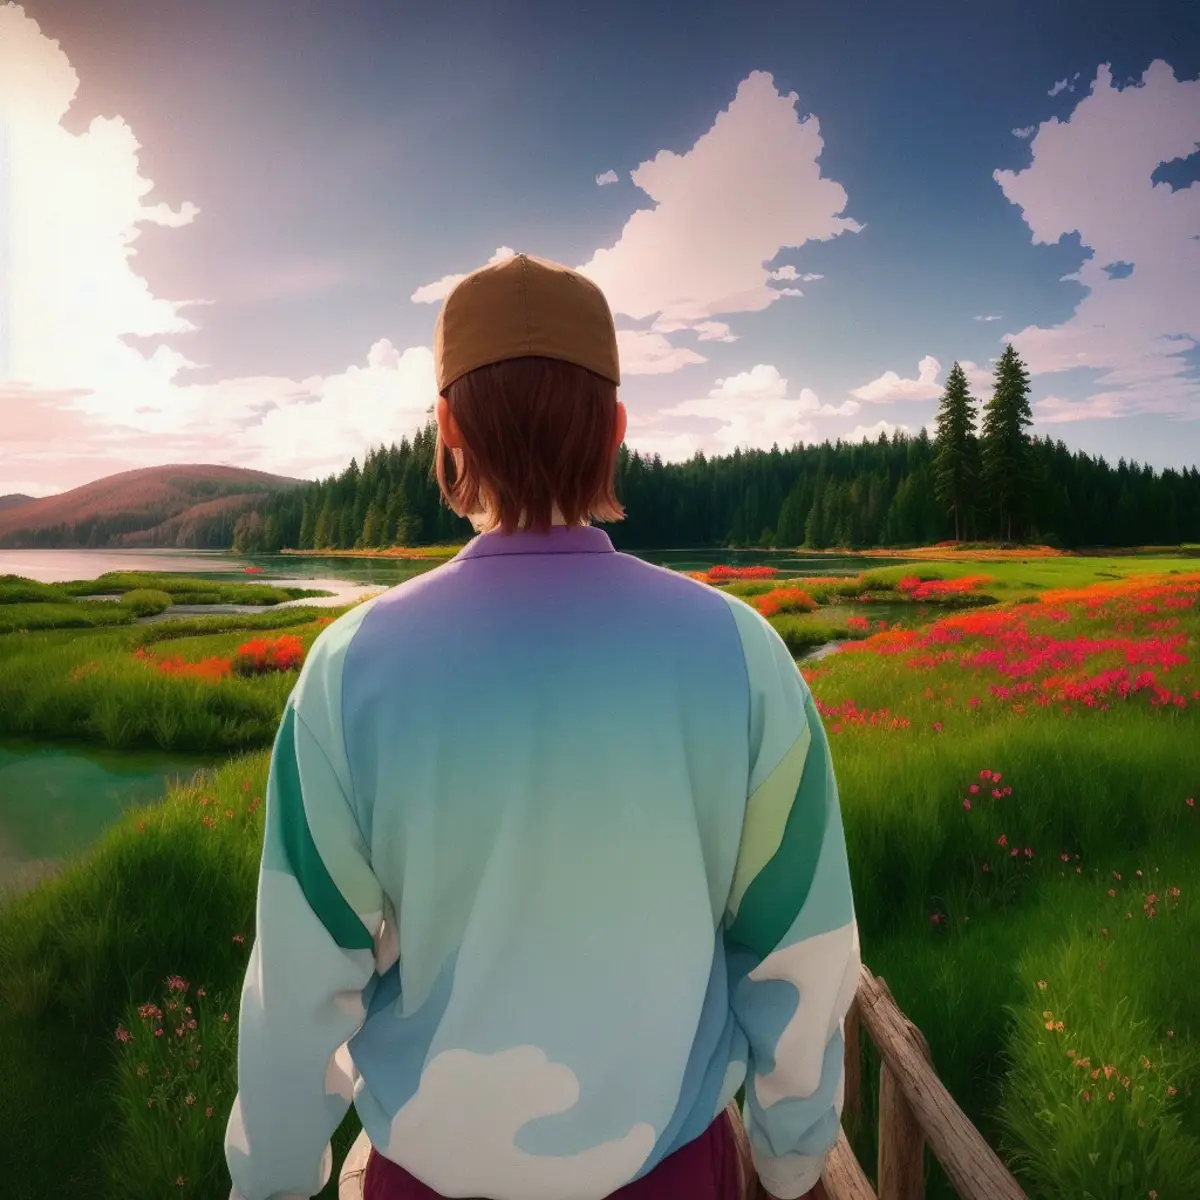 2023 Repaired
It holds up over long stretches, too. The walk away down the boardwalk is about ten seconds of me heading away from the camera, and the dream renders it with the check running the whole way. There's now just the jetty where I was.
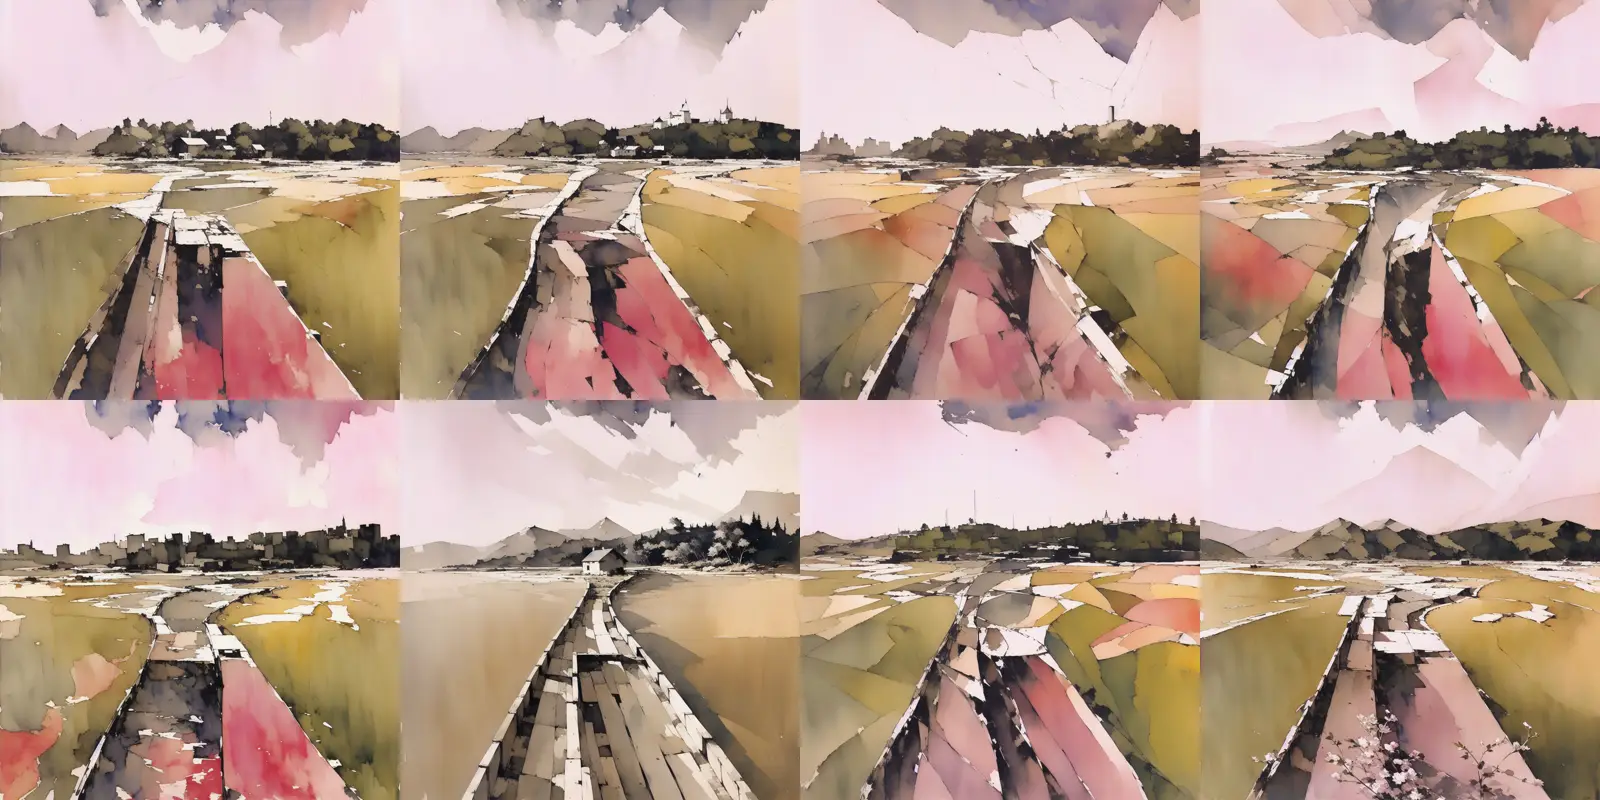
It learned from me a little too well. In 2023 I'd kept the ink-wash busts in Ink Flight and Charcoal, so the classifier learned that a face painted onto a bust was fine. Sharp Edges shipped with a woman's face in about half its frames, and the check passed every one of them. Worse, the repairs kept painting her back in. The culprit was the style image I'd chosen for Sharp Edges: a portrait of a woman, carrying its look onto every frame at full strength. Every new seed politely painted the same face.
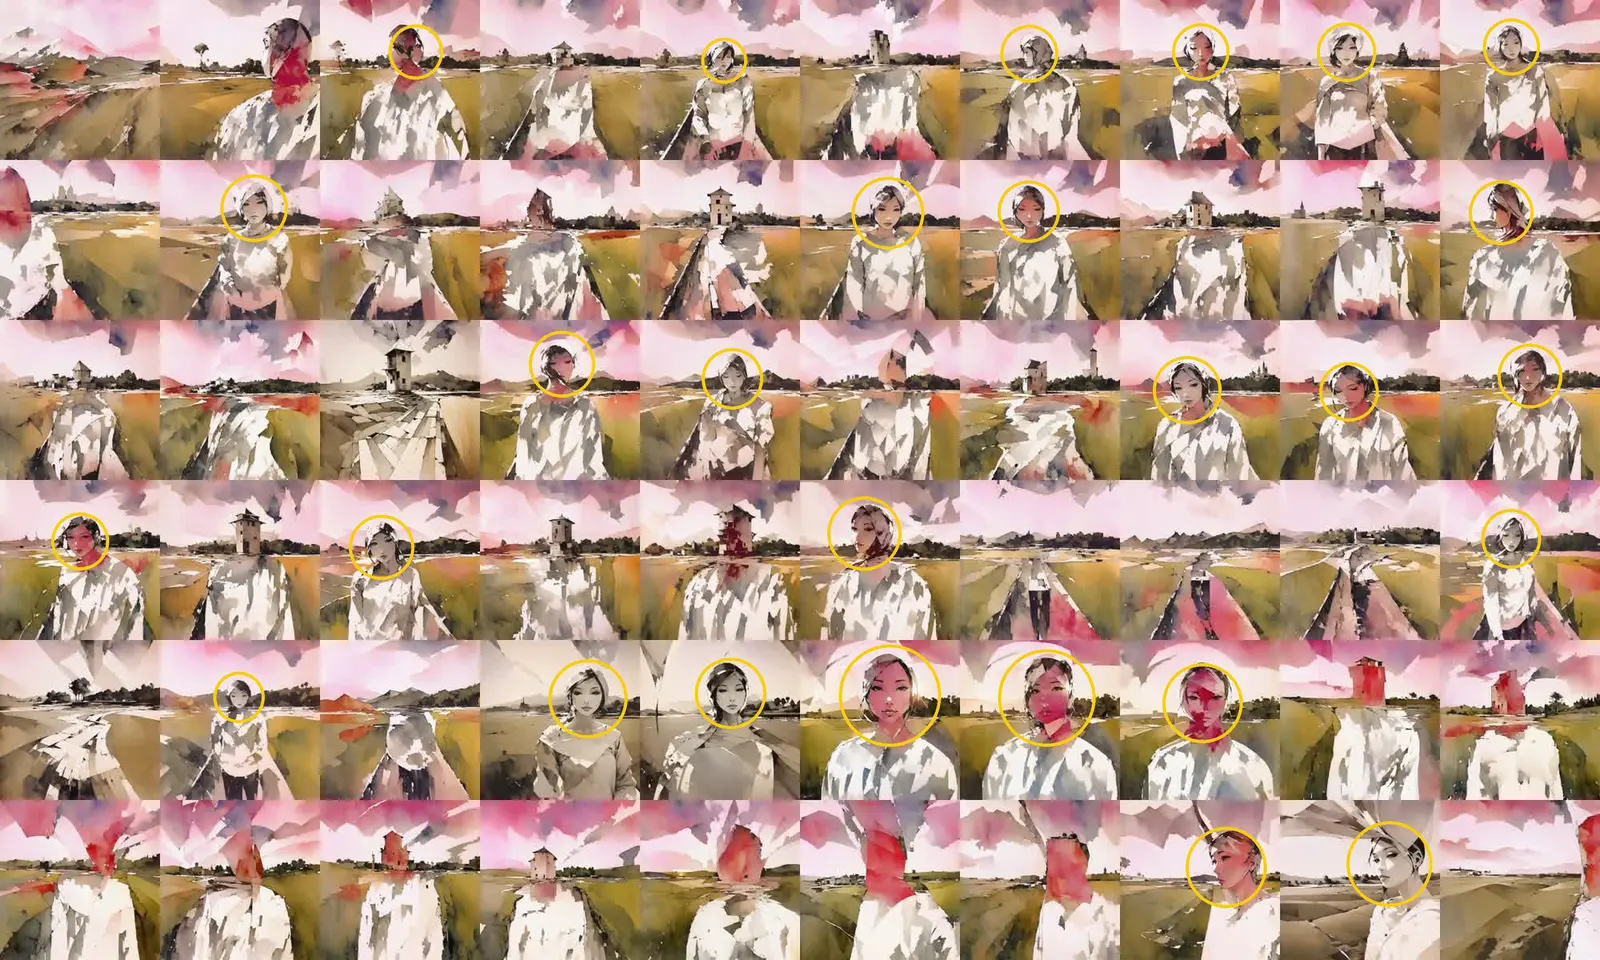
So there's a second check now, a face detector trained on real and illustrated faces, picked from a bake-off on a few hundred frames I labelled by hand. A frame fails if either check flags it. The face detector never decides a re-render, only reports for review, because rerolling until a detector stops seeing a face just finds the faces it can't see. And there's a new rule: never a face in a style image. Re-rendered with a frame of Sharp Edges itself as the style image, the faces in its loop came back as the faceless bust that's meant to be there.
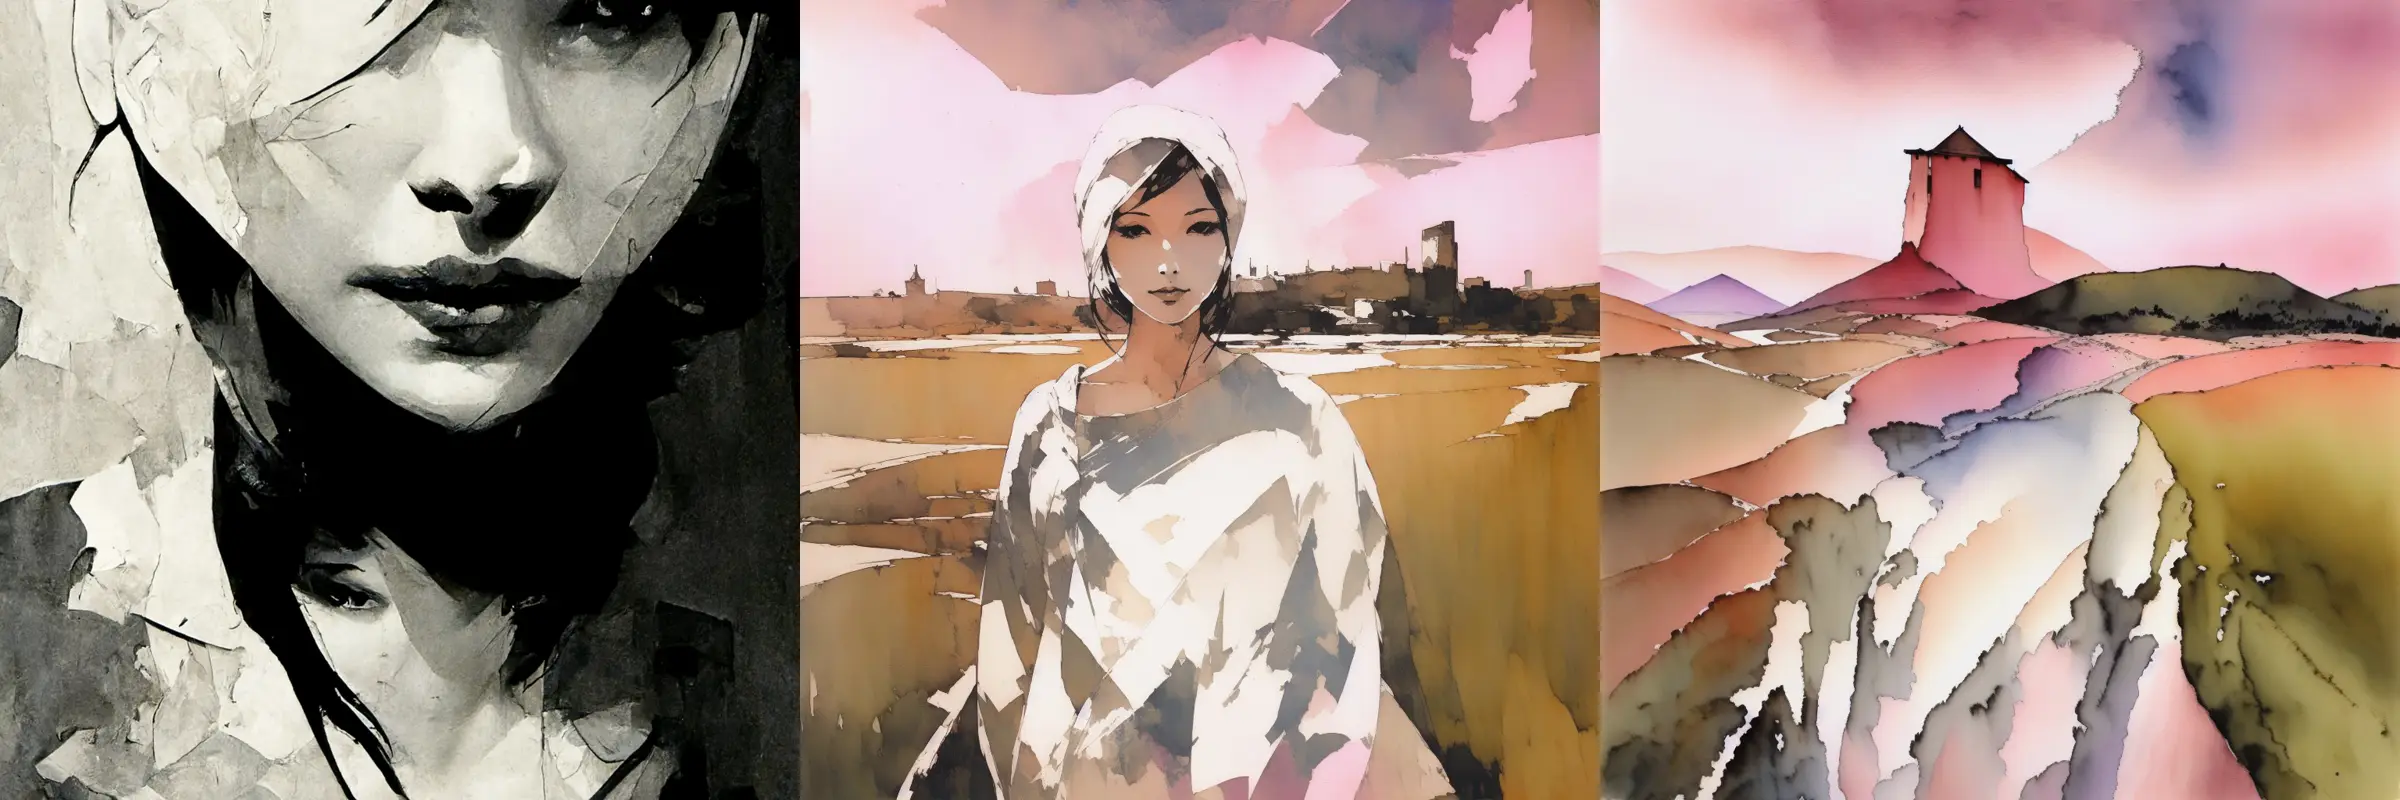
With both checks in place, I went back through all of the original ten, stretch by stretch, and repaired, held, or kept each one. (Charcoal's bust stays. That one's on purpose.)
Making a dream now
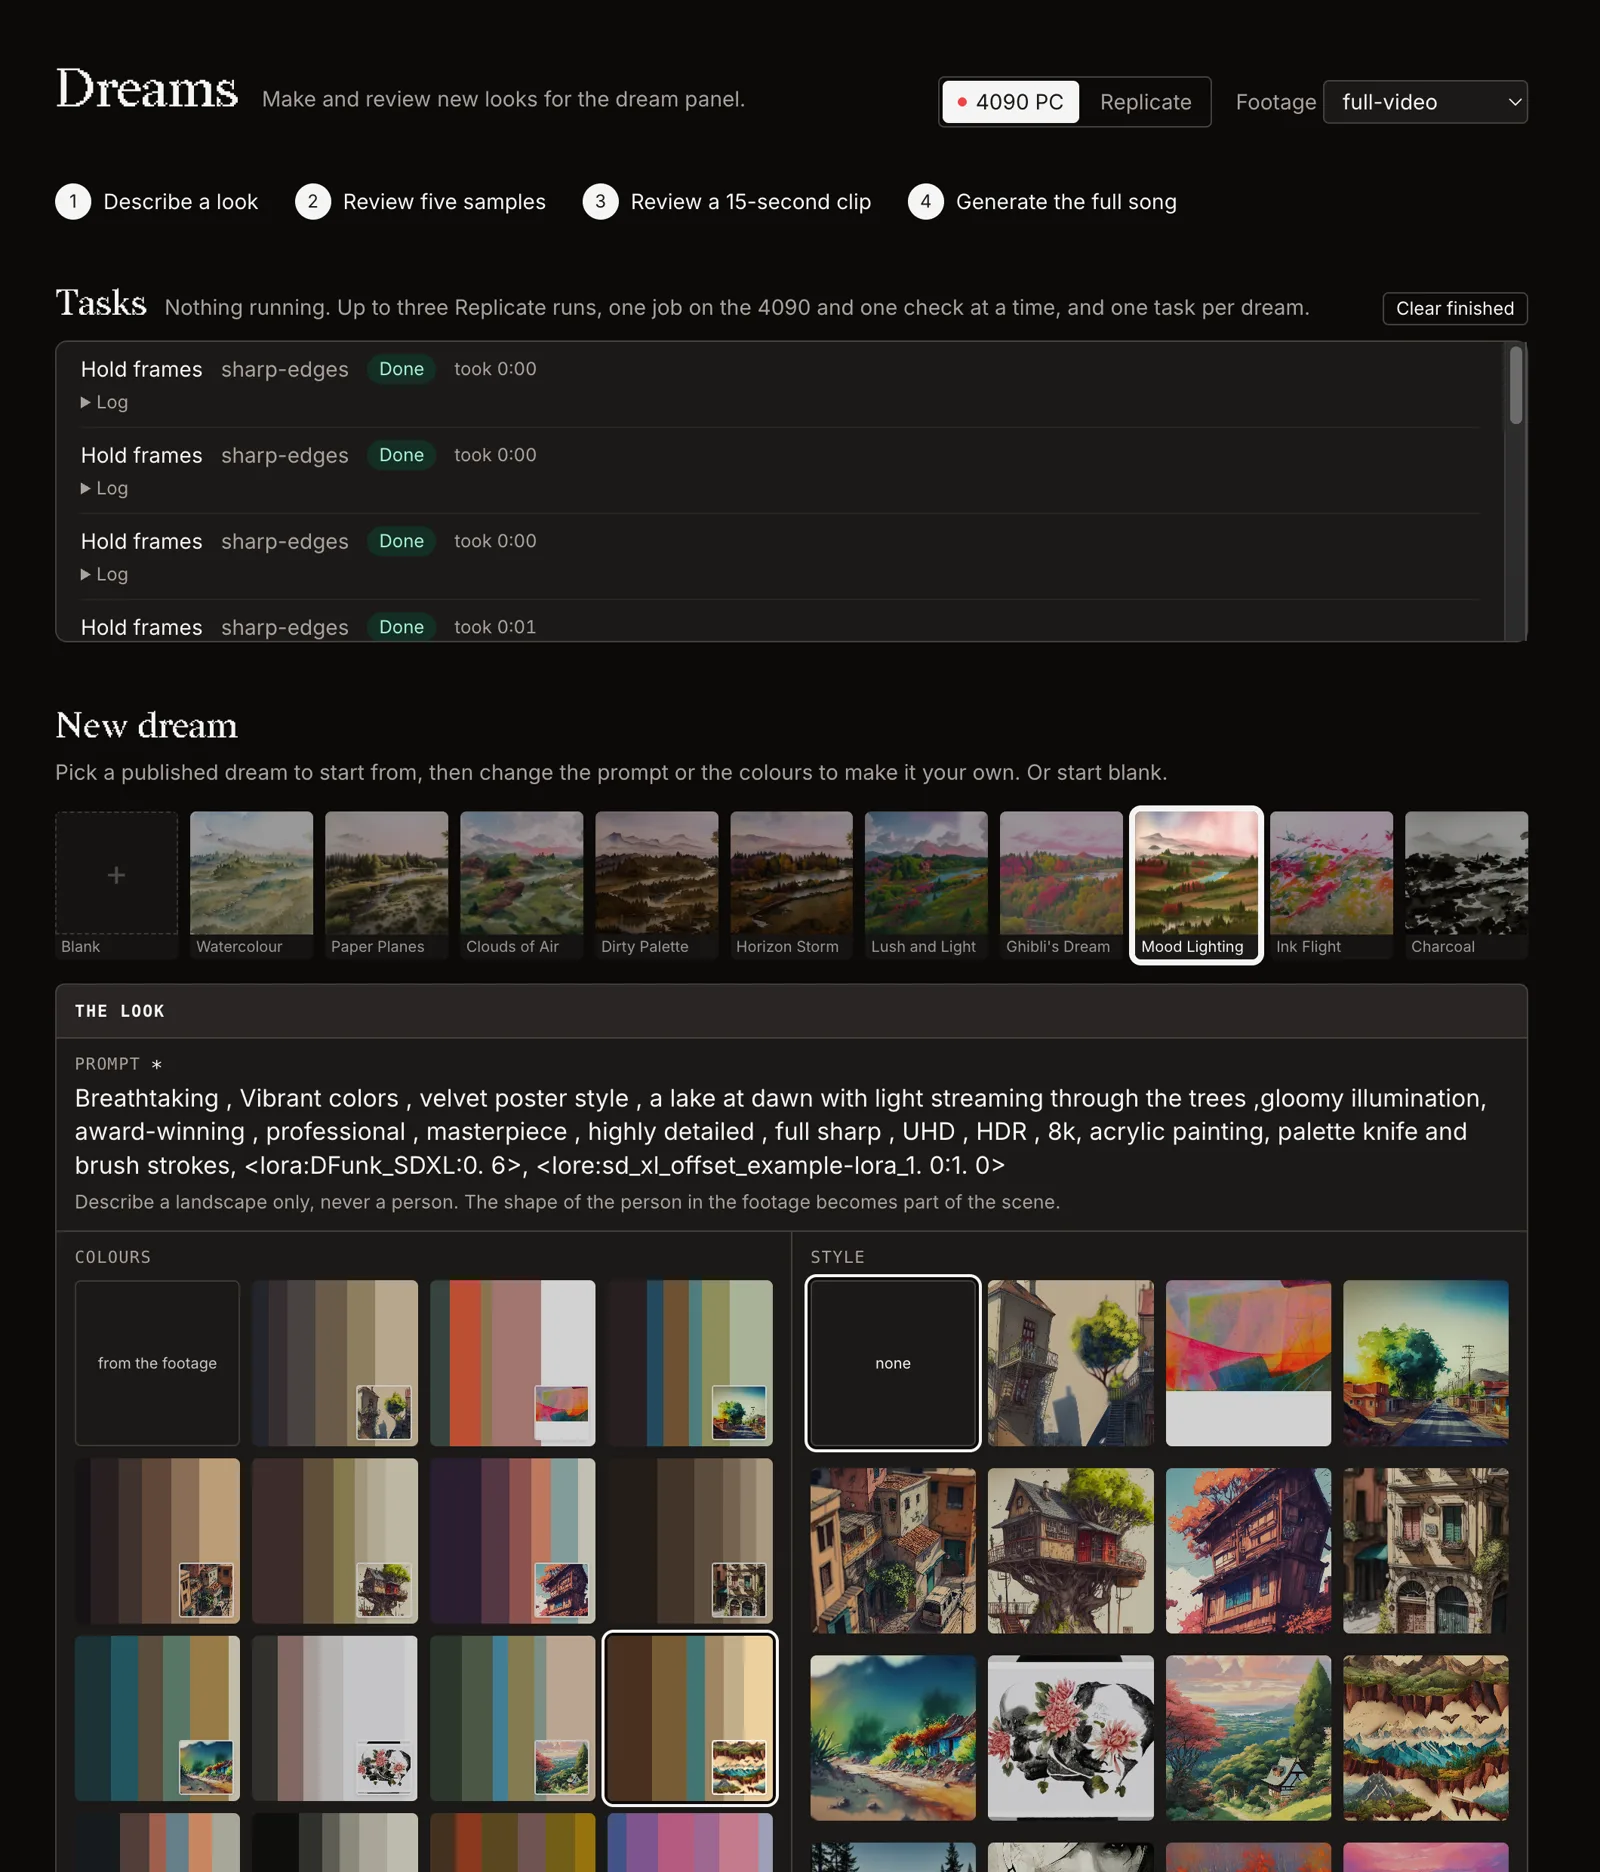
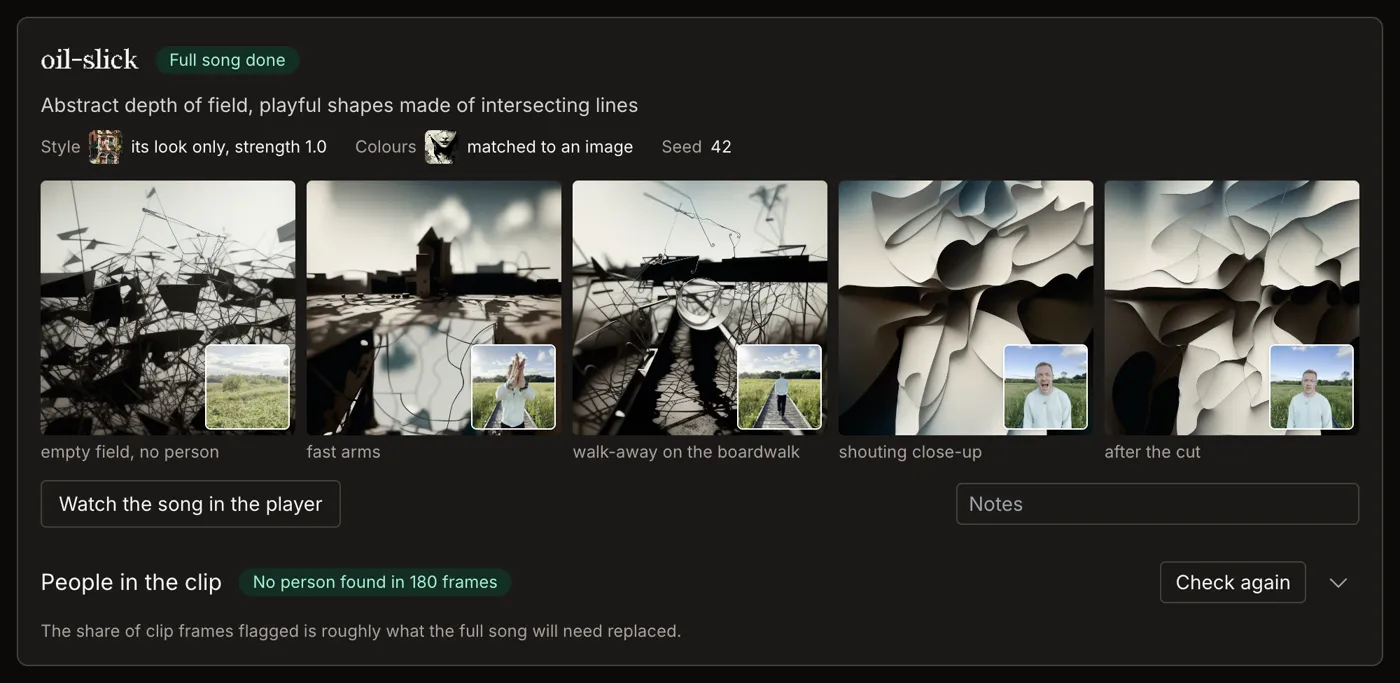
The other lesson came with a receipt: early in the rebuild I paid for two dream takes before noticing that both of them had a person in them. So a new dream is now made in stages, in a development-only page of the app, and each stage has to be approved before the next one costs anything.
- Describe a look. A prompt, a palette image the colours are matched to, and optionally a style image, whose look (but not its content) carries over.
That "but not its content" took some finding. Copied whole, a style image brings its subject along with its look, so a picture of a wooden house puts rooftops on the boardwalk. Copying only its look keeps the dream's own scene.
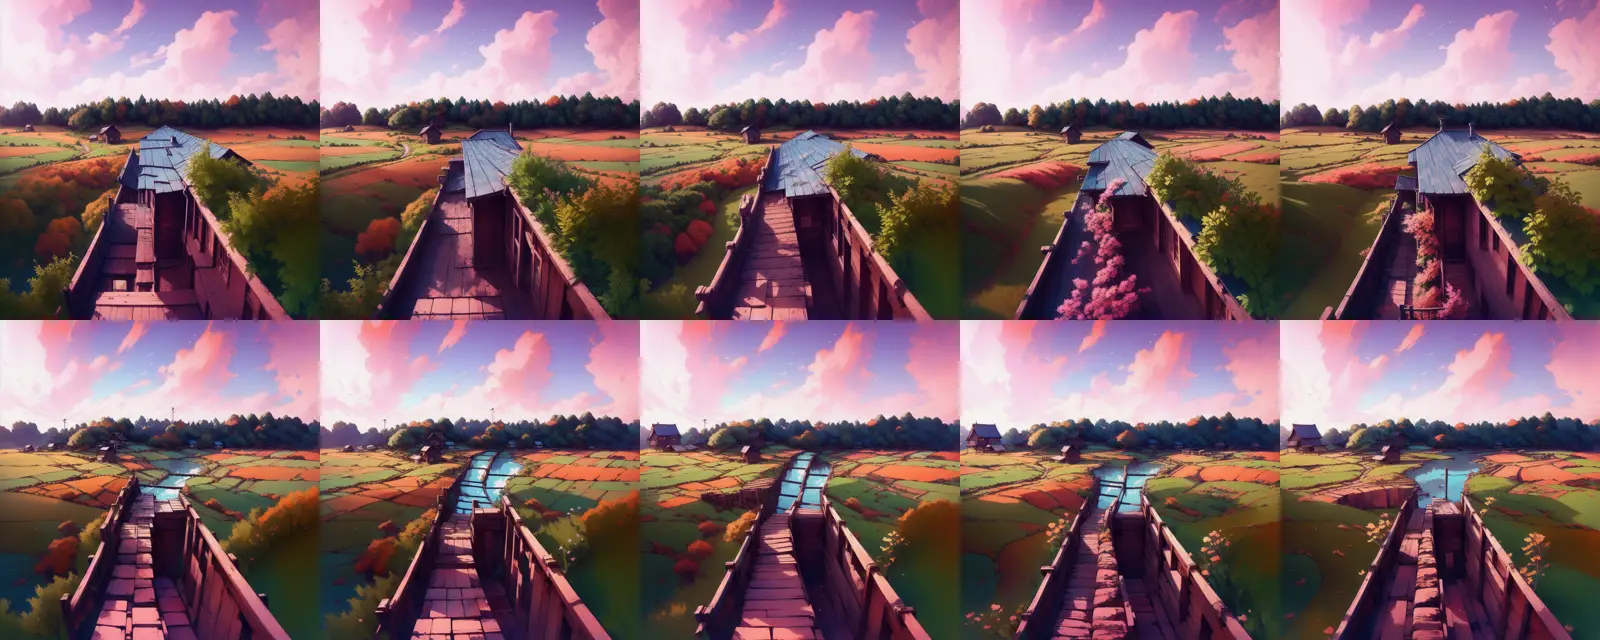
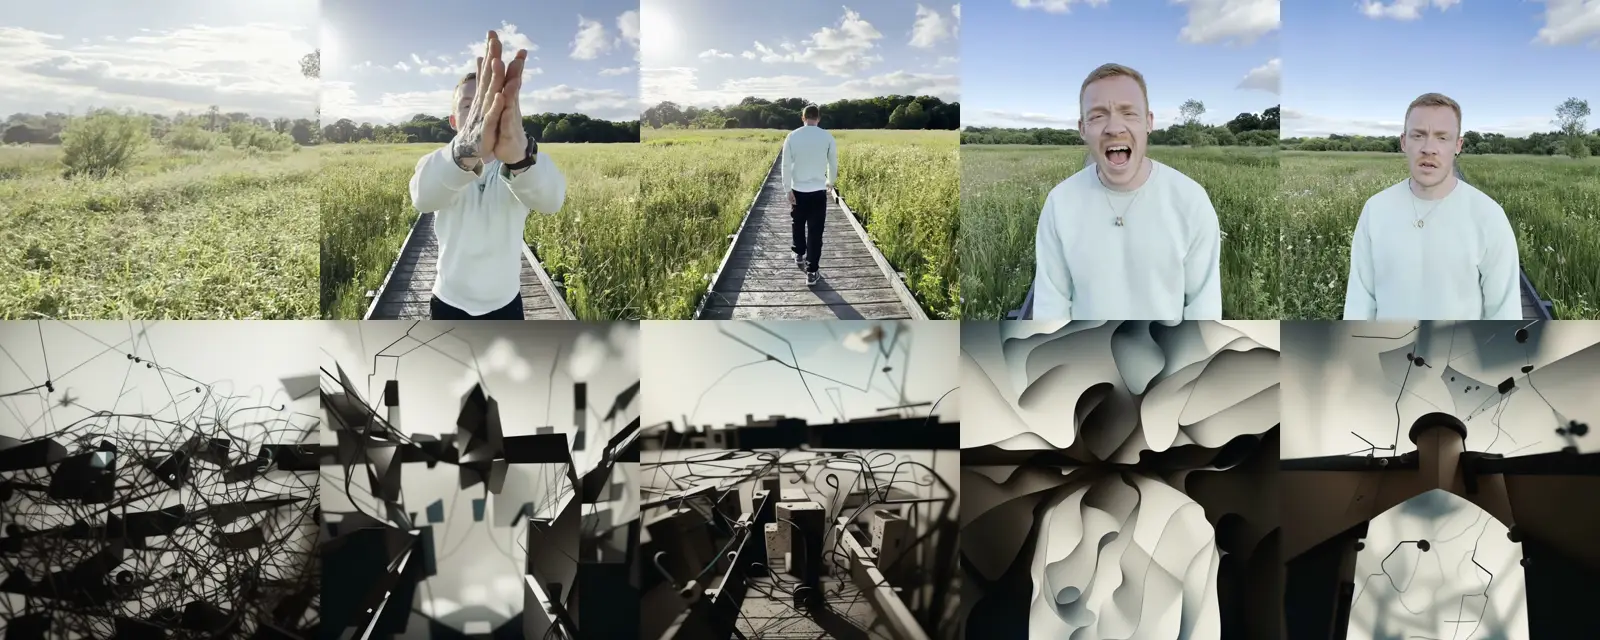
- Review five samples from the hardest moments in the song: the wide intro, fast arms, the walk away, a shouting close-up, and right after a cut.
Those five are where a look tends to fall apart, so they're the quickest way to find out whether one holds up before anything else gets made.
- Review a 15-second clip in the real player. About $1.50, or free on the 4090.
- Generate the full song. About $20 and six hours, then the person check, any repairs, and the final videos.
All in, a new dream costs about $22, which makes "new dreams can be added at any time" true for the first time. Every stage of a take lives on one card in the dream maker, so its whole history is in one place.
The new player
The app got the same treatment, starting with a title that plays the dreams through its letters.
Underneath, it's on React 19 now, with a loading screen where the stack of polaroids builds as the scene loads, and a dream chooser you can toss cards around in. Once you're in, the polaroid itself is the remote: grab it and flick it away, and a blank print develops into the next dream. Flick quickly, and it skips past the ones in between.
Touch got a proper pass too, tested on my own phone: the same cursor ring under your finger, tilt that eases instead of snapping, and water that ripples as you tilt. Every dream also has its own link now, like lysterfieldlake.com/dream/sharp-edges.
Light and dark
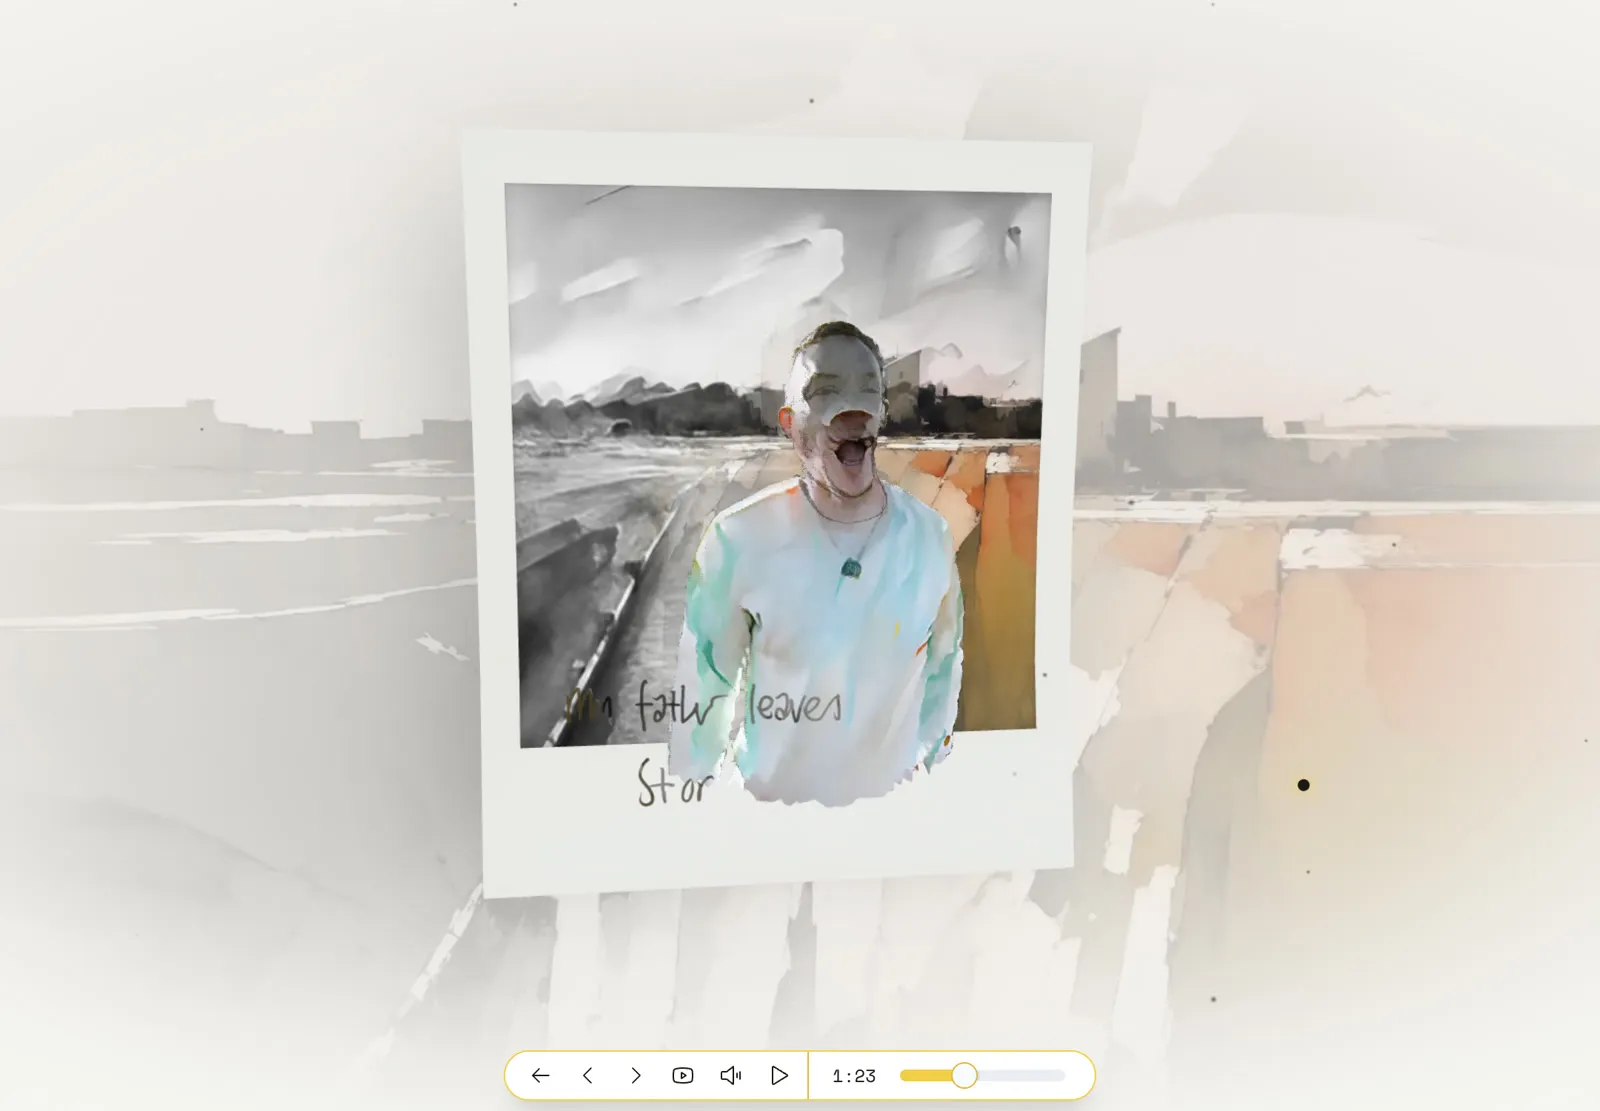
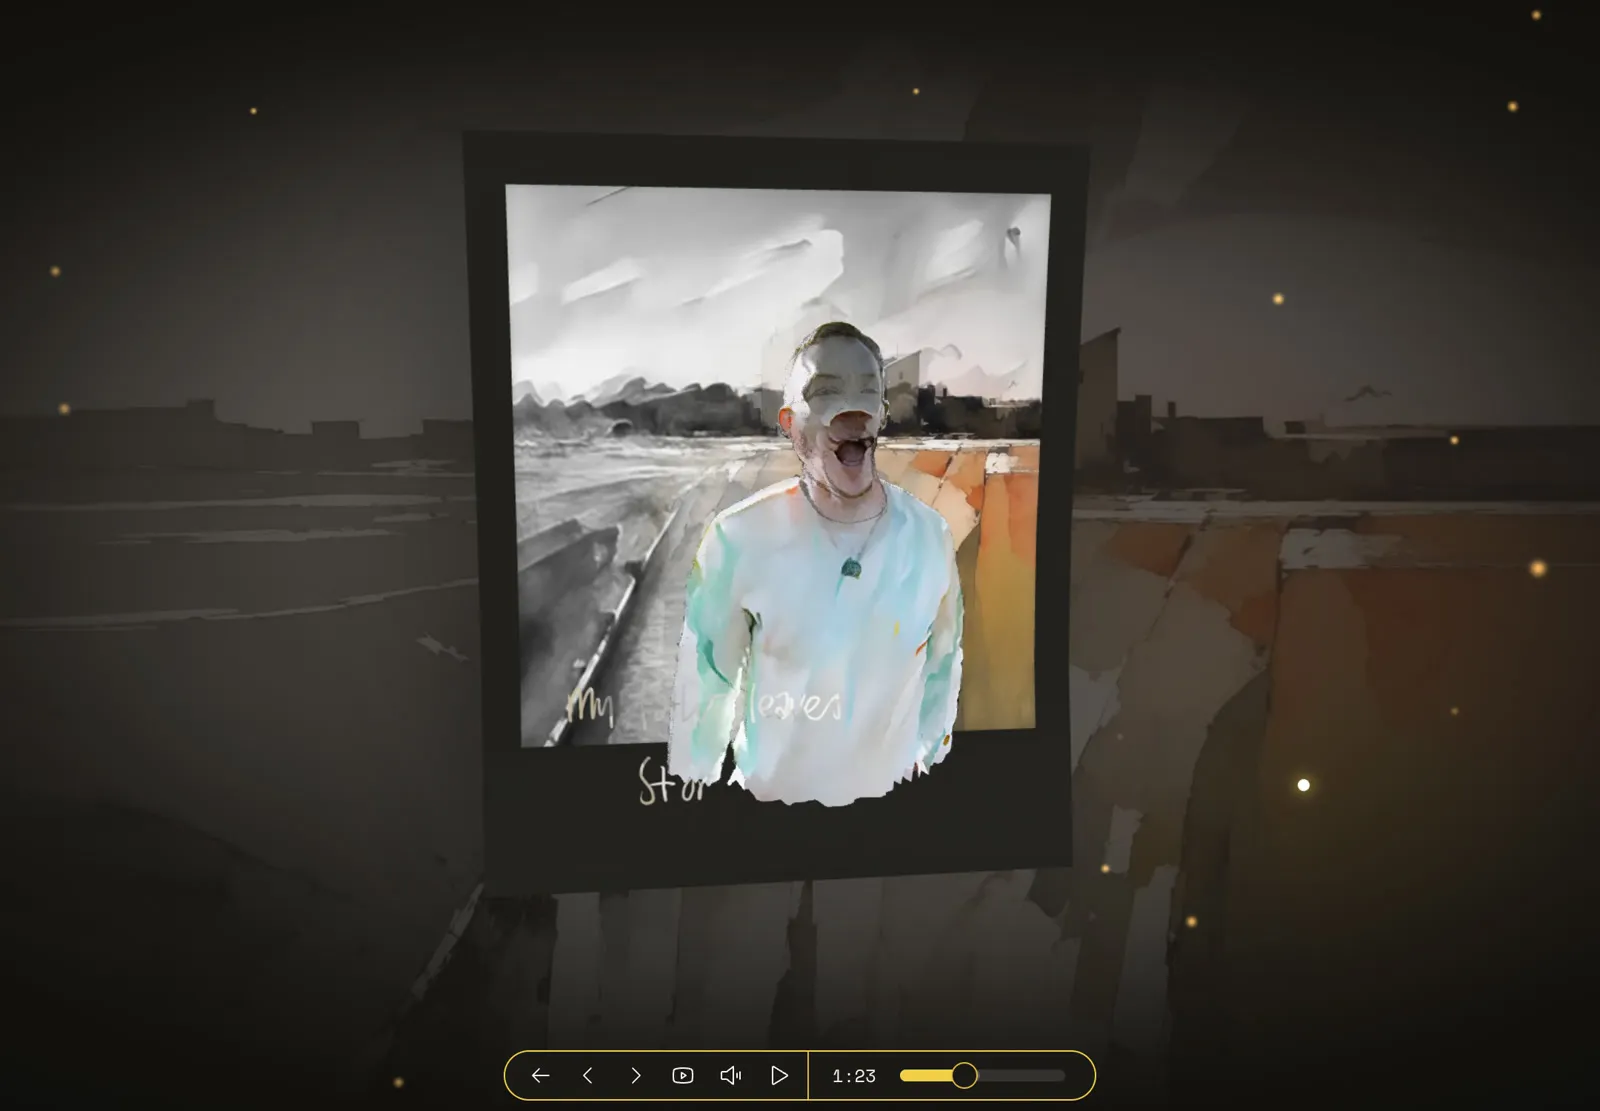
The 2023 version only came in one shade. Now there's a light mode and a dark mode, built from scratch, that follow your system or a three-way toggle in the corner. It's more than swapping the background. The polaroid goes from black card to white paper, the handwritten ink flips from black to white, and the little lights drifting around the scene change species: fireflies at night, gnats during the day.
 Dark Light
Everything else works the same in either mode, including flicking the polaroid to move through the dreams.
Under the hood, the site moved from Cloudflare Pages to a Cloudflare Worker, and the videos now stream from R2.
Things I learned
- The "clean" originals weren't. They were hand-curated, and the rebuild only worked once I'd measured how much.
- Newer models aren't always better for a specific creative job. Sometimes the old one's flaws are the point.
- Removing a GPU can fix a model.
- On Replicate, every model needs its exact version pinned, or it simply isn't there.
- Never write a retry loop against an API that charges per call.
- A visible flaw can ship for three years without anybody noticing, including the person who made it.
- Write down your decisions. Future you is a stranger with none of your context.
Pick up the source
Everything is in github.com/superhighfives/lysterfield-lake: the app, the pipeline, the models, and every plan. You need Bun, and you can have the app running in a couple of minutes.
git clone https://github.com/superhighfives/lysterfield-lake
cd lysterfield-lake
bun install

# Run the app against the published videos
VITE_APP_DREAMS=https://dreams.lysterfieldlake.com bun run --cwd apps/client dev
The videos aren't in git (the main one alone is hundreds of megabytes), so pointing the app at the published ones is the quickest way in. To make your own, give the pipeline a video and a REPLICATE_API_TOKEN in apps/pipeline/.env, and run it a step at a time:
bun run --cwd apps/pipeline cli init --job .jobs/my-video --source ~/development/lysterfield/movies/my-video.mov
bun run --cwd apps/pipeline cli matte --job .jobs/my-video
That's as far as it goes out of the box, though. Each step runs on its own, but making a whole video is more than a dozen of them in the right order, plus things no command does for you: a public R2 bucket for Bria's inputs, a lyrics panel (mine was hand-lettered in After Effects), a bucket of your own to serve the videos from, and swapping my song out of the app. That's the part to hand to an agent. Point Claude Code or similar at the repo and ask it to take a video of yours through the pipeline. The repo's CLAUDE.md and its plans were written for exactly that, including the rules that keep it from spending your Replicate credit twice.
Some useful places to start:
apps/client: the app, in Vite, React, and React Three Fiber.src/materials/video-material.tsxis where the panels get cut apart and put back together.apps/pipeline: the command-line tool, one step per panel.models: the project's own Cog models (Deforum, DiffusionCLIP, line art) and the local person check.plans: every decision, from the first model audit to the relaunch, including what didn't work.
The two original repos, lysterfield-lake-client and lysterfield-lake-pipeline, are archived but still there if you want to see how it was done the first time.
The Conclusion
The selected dream is chopped up and stitched back together in real time in the browser, using React Three Fiber, and many of the incredible resources provided as part of the drei project. You can explore each dream one by one, wandering through a landscape that has been imagined by a computer, listening to a song about a time that sits on the very edge of my consciousness. Memory, like AI, is funny like that.
This is probably a good time to mention that, while this is the conclusion, this project took every possible detour, hit every possible technical hitch, and explored every possible weird twist and turn. What I ended up with was absolutely nothing like what I imagined, because I didn't really know what I was going to get at the end. Which makes it a sort-of love letter to the creative process, and to the joys of pursuing something purely for the "what-if" of it. There are so many ways that sticking with something can truly surprise you, and that doesn't have to involve making weird music videos. It could be baking, or cross stitch, or learning a language, or dance. Things you can experiment with, be creative with, grow with. Things that make you feel like you did something you previously couldn't. Maybe even something great. That might be the greatest feeling there is.
Coming back to it three years later was its own version of that. Like the song says, the tiny changes add up, and you don't notice them until you look back.
I hope you find it inspiring, or at the very least, mildly interesting, and I appreciate you taking the time to learn more about how the project works.
Okay, how do I find out more?

If you'd like to check it out, you can do so here:
https://lysterfieldlake.com/
If you'd like to share this project, that would be greatly appreciated. The project itself is entirely open-source:
👉 lysterfield-lake
The app, the pipeline, the models, and the plans, all in one place.
(Author's note: In 2023 I warned that it wasn't the cleanest code, and that the pipeline wouldn't work locally out of the box. The second part is fixed, and the first part is better. It's still a passion project rather than an example of how React should be written, but this time it's one you can actually pick up and run. Cheers. 😅)